
TUBS was previously funded by NLNet. The TUBS vision now provides background for ongoing work on ontola/atomic-plugins.
Typed data, versioned together with its schemas, across hosts, protocols and agents. TUBS starts with bookkeeping and explores a broader foundation for software: durable data, messages and computation that can move between independently operated services. People should be able to change an app, a storage provider or a worker while preserving their data and ongoing work.
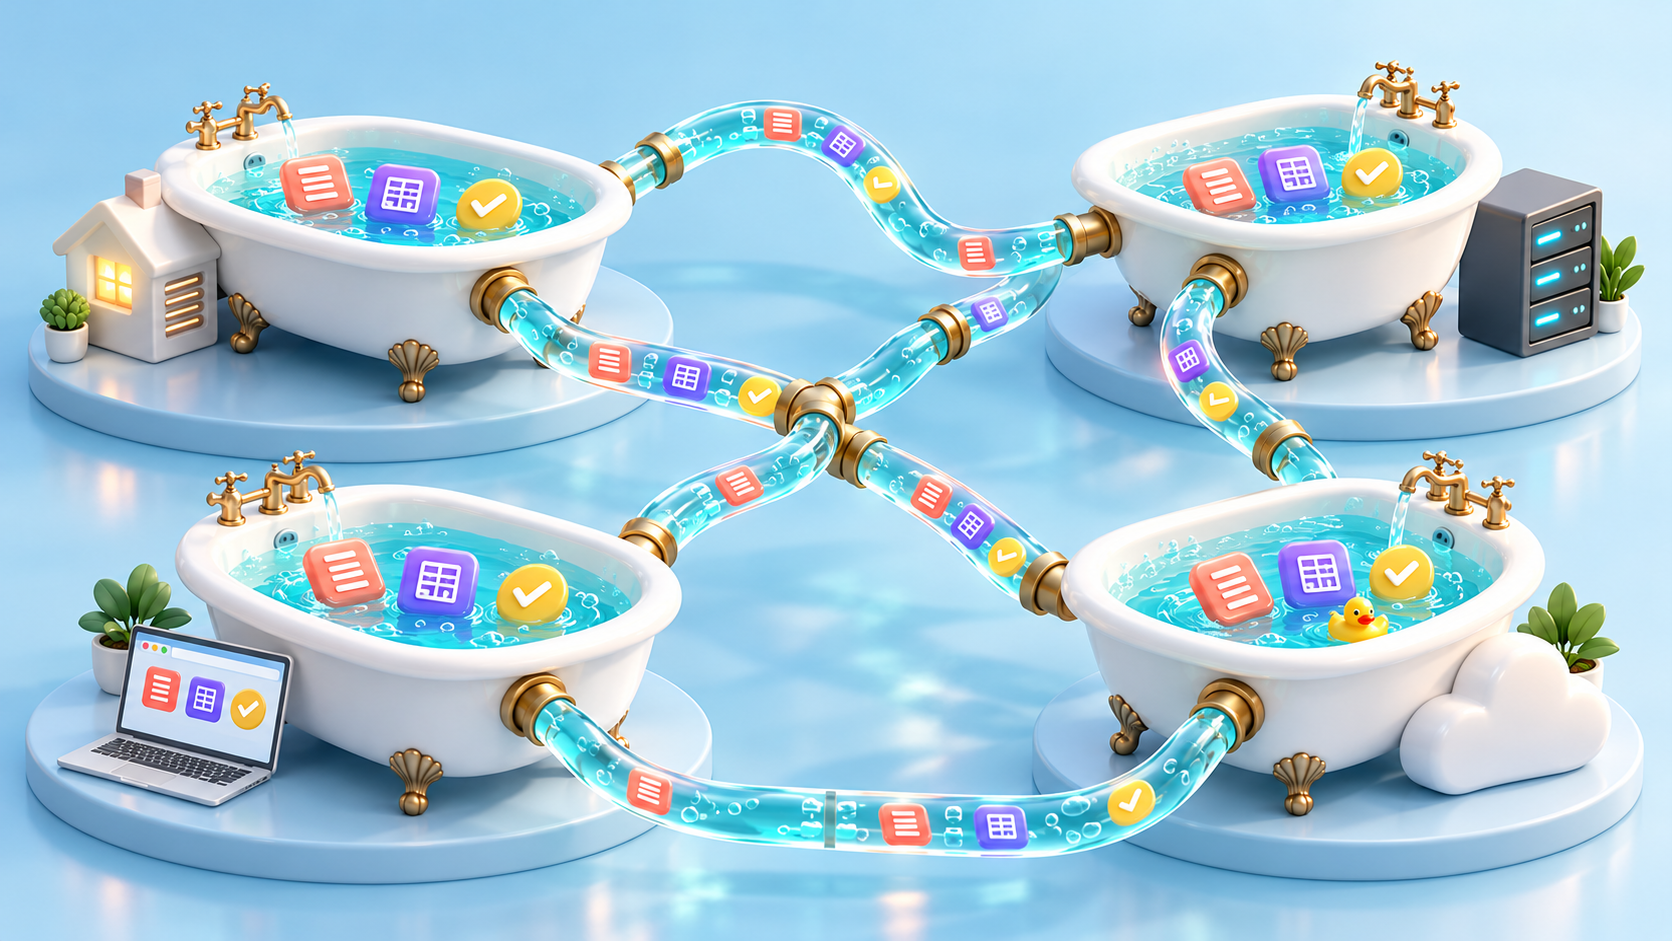
This is a direction for research and implementation. The components below are building blocks toward it; the full set of guarantees is still being developed.
Messages, tasks and results carry these identities and versions across systems. A worker can state which input versions it accepts, which protocol or implementation version it uses, and which effects it is authorized to produce.
Your bookkeeping data already lives in many places: your bank, your invoicing tool, your time tracker, your accountant's package. A record should be able to live in several systems at once, with explicit rules for reconciling changes. You could keep a local copy, use a personal data store and maintain backups with other providers. An unhosted app can run in your browser and connect to the stores you choose. Its operator need not hold your application data.
Existing and ongoing work makes data behind an API available as a local copy, using reusable descriptions of how each service works:
SyncD is the standalone Syncables daemon. It uses the generic API client to read configured collections and keep a local, versioned archive of data from APIs. Successive reads create snapshots, preserving earlier records and their accompanying schema resources as the source changes. You can browse the archived data offline and inspect a particular revision rather than relying only on what a service returns today.
PostgreSQL holds the archive and its history; working folders expose the local data, and optional Git exports make collection or item histories available to repository tools. SyncD retains source JSON alongside the Atomic Data representation. The current standalone daemon reads and archives provider data; sending local edits back is supported separately by the Syncables library where the API and its description allow it.
Atomic Lenses (also known as Devonian) will help set up the tubing between tubs that use a given Atomic schema. A lens describes how a platform's records map to that schema's classes and properties, and how supported changes map back. Identity mappings keep track of which records in different systems correspond.
For example, two bookkeeping services may represent an invoice differently. With a lens from each service to the same Atomic invoice schema, applications can work with a shared representation, and a sync workflow can translate changes into the other service's format. Each service can have its own mapping to the schema, reducing the need for a separate integration for every pair of services. Lens mappings can preserve source fields that the shared view does not expose.
This is ongoing work: lenses supply the mappings, while the surrounding workflow supplies permissions, scheduling and conflict handling. Reflector is the sync engine for keeping copies in step. Together, these projects connect existing services to the broader multi-homed data vision.
Applications need to know which guarantees each component provides, who enforces them and under which failure assumptions. These contracts let a workflow choose suitable components across different hosts and protocols.
A Solid Pod with an appropriately configured inbox could receive messages while its owner is offline. Their browser or a separately hosted personal worker could process them later. Atomic sync could provide another route for exchanging changes. A successful inbox delivery establishes receipt by that store; the application protocol determines when a participant has agreed to a transaction. These are possible integrations to explore.
Together, these pieces suggest a kind of world computer assembled from independent stores, messaging services and workers. Each workflow chooses the consistency and trust guarantees it needs. People, deterministic programs and AI agents can participate through the same typed, versioned interfaces, with their authority explicitly bounded.
Like a spreadsheet, some values are formulas over other values: an invoice total, an account balance, the VAT for a quarter. The design principle is to retain the formula and its inputs, with cached results where useful. When copies from different systems are merged, a stored total can silently go stale; a formula is recomputed from the merged data.
The same idea covers the rules of bookkeeping. An invariant, such as "the balance equals the sum of the transactions", is a computed cell that must be true. TUBS aims to make violations visible for review. Rules that must hold before an action takes effect, such as spending limits, also need enforcement in the transaction protocol.
Like a Git repository, the aim is to retain state and its history, with a message explaining each change: "marked invoice 2026-041 as paid, matched to bank line 3812". Changes proposed by people, apps and AI agents should record their author, relevant input and type versions, and intent. This supports review before application and tracing afterwards, according to the workflow's authorization and retention rules.
The purpose is to increase people's agency over their software and records. Workers should receive only the permissions needed for a task, with bounded delegation. Automation should be inspectable, and people should be able to stop future actions and withdraw authority. Completed actions and copies already distributed may remain irreversible.
Open formats, portable identities and documented protocols should make it possible to move data and pending work between providers. Participation should allow independent operators and identities. As the architecture grows, we ask whose agency a feature increases, what authority it creates, and how that authority can be withdrawn.